CHALLENGE 01
Photos that could land on the wrong house
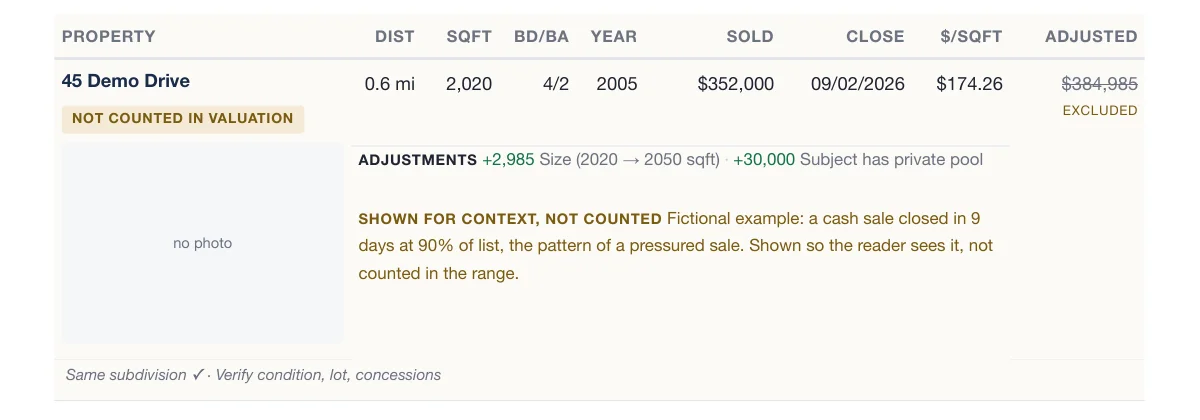
Listing photos are pulled out of a PDF report, and the photo for each page is matched to a listing by position. The first extractor sometimes cut images short.
VERIFIEDOn a real seven-listing export, all seven photos came out byte-identical to a hand-extracted reference set, and all three failure paths exit with a specific message.
Why it was hard, what I decided, how AI helped
- Why it was hard
- It searched the raw PDF for the byte marker that ends a JPEG, but that marker can also appear inside the image data. A short fragment fell under the size filter and was dropped, so every later photo shifted onto the wrong listing, with no error.
- My approach
- I treated it as a client-facing risk: the wrong house beside a comp in a seller's report is worse than a missing photo.
- How AI helped
- Claude Code replaced the extractor with poppler's pdfimages, run one page at a time so the page-to-listing mapping never depends on file numbering. It added guards that stop instead of guessing.
- The decision
- Fail loudly. The run stops if the page count does not match the listing count, if a page has more than one photo, or if a saved image does not decode.
- Evidence
- commit b05d0aa (12 Aug 2026)